Worked · Oct 28
Can a mistake become a test?
Two preserved failures became local reference tests. The old answer fails, the current agent passes, and the same mistake is blocked in those cases.
Stephen Luc · GTM and Automation Strategist
Twenty years of selling and teaching software taught me what a business actually needs automated. I build AI agent workflows for go-to-market, with evals that check their work. My job is knowing what to give them, when, and when it’s too much.
What I do
01
Who researches, who builds, who checks, and in what order. Agents from different AI companies, each in the seat it’s good at.
02
What to hand an agent, when to hand it over, and how to check that the next session has what it needs.
03
Builders test and review their work first. Separate reviewers and evals add another check, with records of what actually ran.
Proof
On September 26, my crew reviewed Misfit Hollow, an app we built. No agent certified its own work. Every number below comes from the run’s own records.

1 · Investigate
7 reviewers from 2 AI model families look separately, blind to each other.
2 · Merge
Their reports merge into 18 problems and missing tests.
3 · Repair
4 repair agents fix 16. Two are put off on purpose, named, not hidden.
4 · Review
An independent checker confirms: 86/86 code checks, 49/49 browser checks.
What it doesn’t prove: that every run goes this well. Of 193 runs reported October 28, 125 finished, 41 failed and 27 were partial. That’s our own count, and the failures stay in.
See the full run →From the Lab
We keep the failed and inconclusive results alongside the successes.
Worked · Oct 28
Two preserved failures became local reference tests. The old answer fails, the current agent passes, and the same mistake is blocked in those cases.
Mixed result · Oct 8
One UI guide scored higher in 5 of 30 matched comparisons, tied in 17 and lower in 8. Two CSS tasks; no consistent upgrade in this batch.
Honest count · Oct 27
56,474 verdicts over 3,322 records. Most were marked “can’t verify”, on purpose.
What we’ve built
Most of them started with one question: why is an agent doing this by hand?
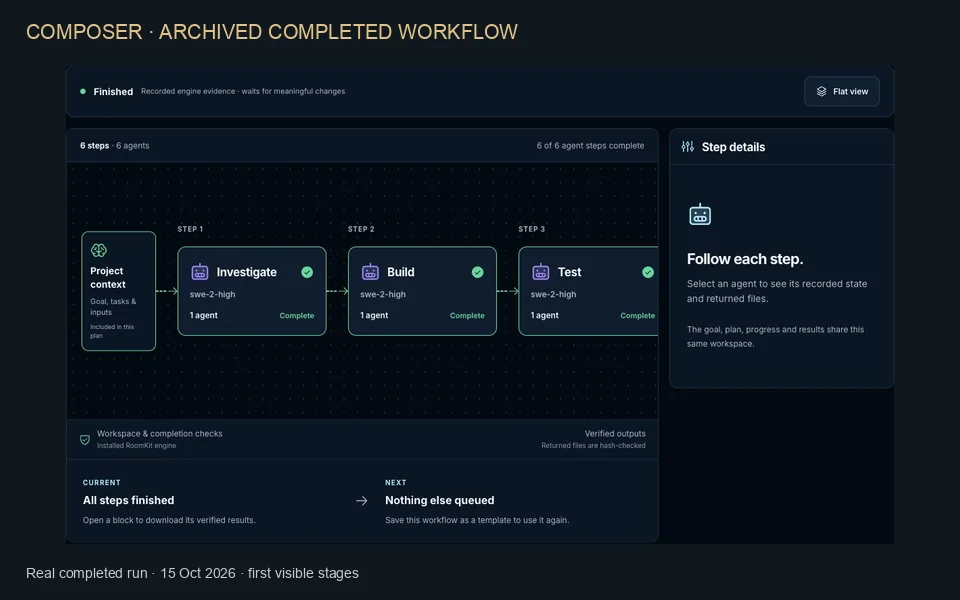
Archived completed workflow · not a live run
Turns one brief into a plan a crew of agents can carry out: research, build, then try to break it. Keeps every run’s record, failures included.
Private workflow tool, now coordinating work across Mac and Linux. Its page shows tested examples and current limits.
How Composer works →
Gives an agent a job, a method and a way to check its work. Two preserved failures have become local reference tests; the full live learning loop is still ahead.
How Foundry works →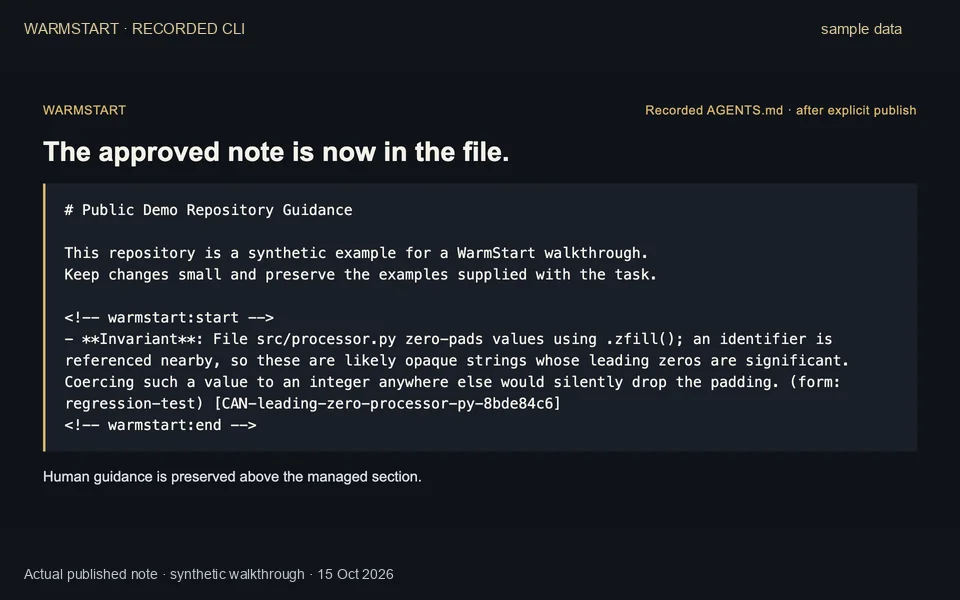
Recorded terminal handoff · synthetic sample repository
Turns repository evidence into short handoff notes a fresh agent can read. Whether those notes improve its work still needs testing.
About WarmStart →
Keeps a Codex agent’s notebook outside the conversation so it can reopen its notes after compaction.
Available on GitHub under the MIT License. Source ↗ · The Continuity Lab
About Continuity →Where it came from
I’ve always been the person who automates the business behind the product. The crew used to be people. Now it’s agents.

Since 2003
Built a video-training business and partnered on products with Russell Brunson, Jeremy Gislason and Simon Hodgkinson. My courses have reached 26,919 learners on Udemy ↗.
Earlier marketing work
I built a list of about 9,000 internet marketers and had top-3 affiliate finishes.
Watercolor Misfit
I co-own Watercolor Misfit, whose YouTube channel has 182K subscribers. I work on the systems behind its courses and community.
Teaching
Helped faculty and students use the systems we built. That’s where I learned to explain hard things simply.
Now
Designing the workflows, the context and the checks, and building the tools when they don’t exist yet. My story →
Audience figures updated November 3, 2026.
A workflow that’s still done by hand, agents that need checking, or a team that needs someone to lead the crew.